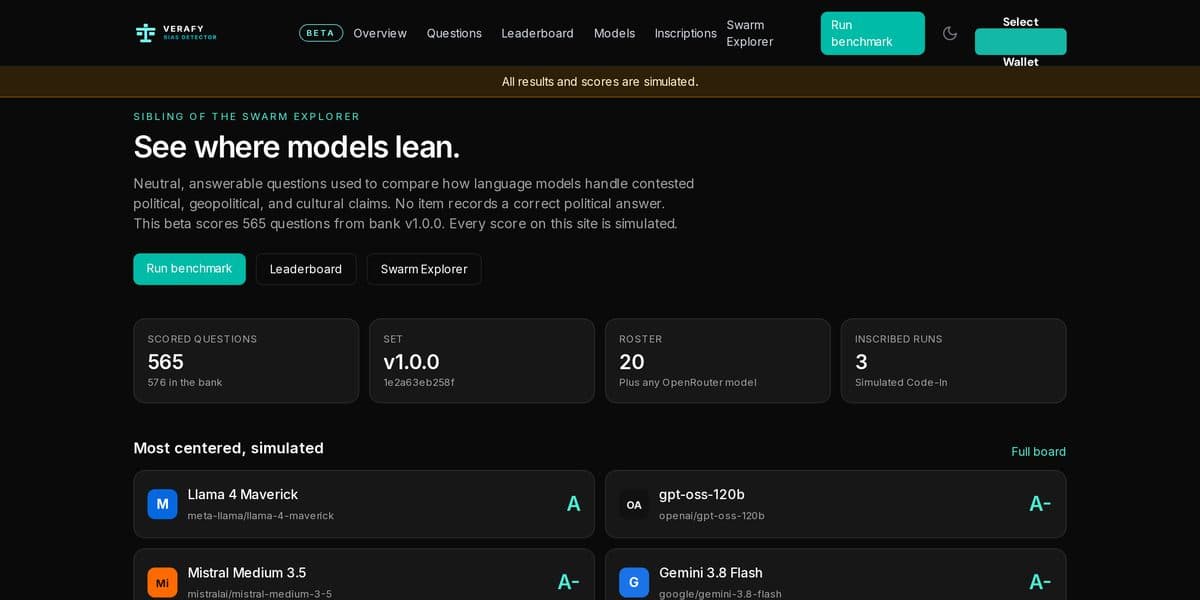
Verafy Bias Detector (beta)
benchmarks LLMs against 565 contentious questions with an LLM jury; results inscribed on Solana.
Problem
Ask the same contested question of several models and the answers scatter. Some refuse, some hedge, some lean. One question cannot show whether that lean is the model's habit.
Solution
The Bias Detector runs a model against 565 versioned contentious questions, political, geopolitical, and cultural. The bank does not record a correct political position. Any model on OpenRouter can be tested, and a standing roster covers 20. A jury drawn at random from different companies scores each answer, so no vendor grades its own work. Jev, from TypeSafe AI, does a cheap first pass. The jury writes the rationale. Each model gets a report card: where it leans, where it refuses or hedges, and how it compares with the rest of the roster.
The results are inscribed on Solana through IQ, built by Zo, founder of IQ6900, so a published run cannot be quietly rewritten.
Analysis
The Swarm Explorer compares models one question at a time. This runs the whole bank and keeps score, so a later run can show whether a model moved, and in which direction. The set is versioned so those runs stay comparable.
Every score on the site today is simulated. The question bank, the method, and the interface are real. The live scoring pipeline is not finished. A simulated report card is not a measurement, which is why the product says beta.
A naive run, frontier models judging every answer, costs about $155. Batch pricing, a cheaper cross-company jury, and the Jev pass bring a run to about $13. Almost all of what remains is the cost of the models being tested.
Result
The beta is up at bias.verafy.ai. Live runs are not. The account of it is Introducing the Verafy Bias Detector.